The model and its training sources
Heatpoints uses UNISAL, published at ECCV 2020. The implementation supports an eye configuration with MIT1003 fine-tuned weights and a mouse configuration with SALICON weights. The v1 image tool explicitly uses the eye configuration.
SALICON uses mouse-contingent data as a proxy for visual attention. It must not be described as a dataset consisting entirely of direct eye-tracker measurements. The distinction between weights matters, and the model predicts a distribution rather than measuring a new participant.
References: UNISAL publication and code · SALICON, CVPR 2015
Processing changes the map
The v1 pipeline uses overlapping windows for sufficiently tall images and percentile normalisation. The baseline configuration uses a different single-pass resize and normalisation. A long-page image and a viewport capture can therefore produce different maps even when they show some of the same content.
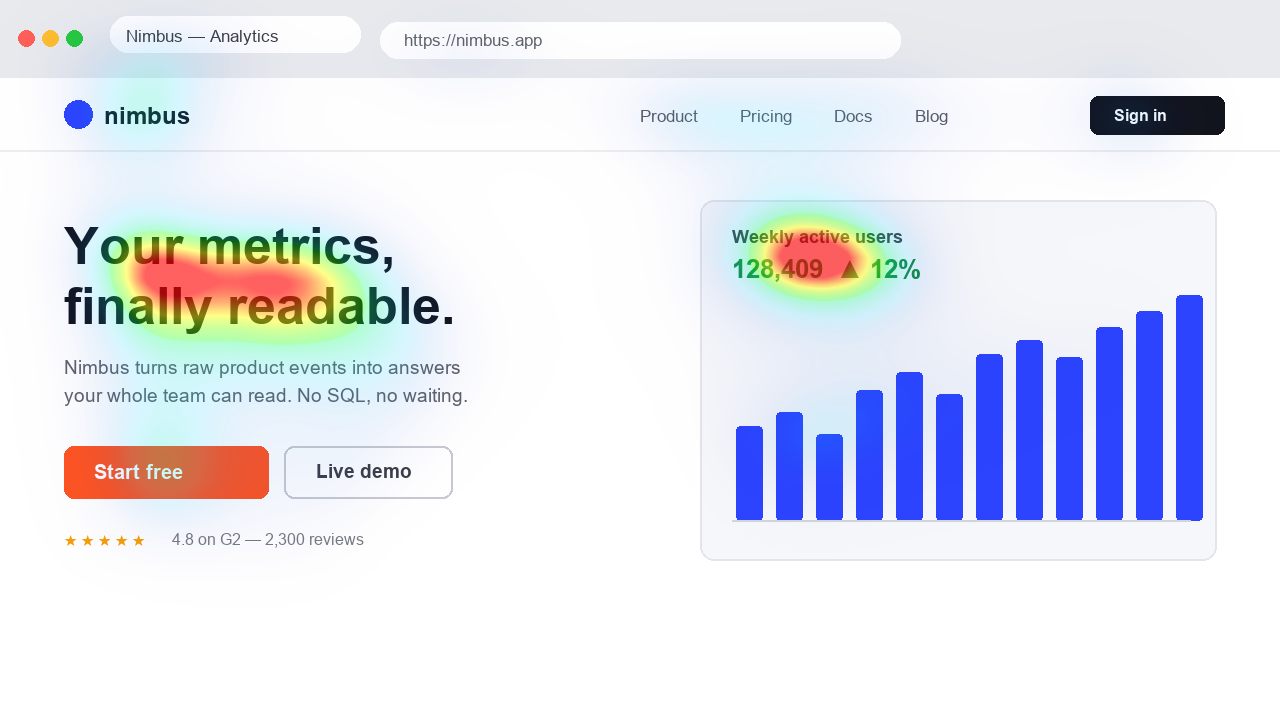
Colours are relative to the normalised map. They cannot be read as an absolute quantity of attention across unrelated images. For comparison, keep the input dimensions, crop, engine and weight configuration consistent.
Metric definitions
Attention in the image tool is mean normalised intensity, scaled to 100. It is not the percentage of visitors looking at the image. Focus is derived from the standard deviation of intensity values; it measures intensity variation, not the spatial dispersion or number of fixations.
Coverage is the percentage of pixels above 0.3 normalised intensity. Hierarchy compares the highest and second-highest mean intensities in a three-by-three grid, scales their ratio and caps the result at 100. The primary zone is the grid cell with the highest mean.
A grid cell is not a detected button, face or hero section. The boundaries are geometric. A small object can share a cell with unrelated content, and moving an object across a cell boundary can alter the summary.
Why scores differ between tools
The simple image tool shows mean-intensity attention. Championship and creative scoring use a composite: 35% of attention scaled by four and capped at 100, plus 35% hierarchy and 30% focus, rounded and bounded to 0–100. Coverage is reported separately and is not part of that composite.
Do not compare the image tool's attention value with a Championship composite as though they were the same measure. A composite is a chosen summary of a map, not a scientifically calibrated probability of success.
What has not been established
Heatpoints does not claim a universal accuracy percentage, an individual gaze path, a reading order or predicted CTR. Academic benchmark results depend on a specific model, dataset and evaluation protocol. They should not be transferred to every production screenshot as a marketing accuracy badge.
A repeated input with fixed weights and processing can be checked for deterministic output. That does not imply identical maps across engines, devices, software versions or differently captured pages. Important decisions should be validated with the intended users and an outcome-appropriate method.